Artificial Intelligence is both a topic of Computer Science and Philosophy, and begins to ask what really makes us human and if we are just a complex biological machine? Alan Turing first asked the question in his 1950 paper named Computing Machinery and Intelligence. The paper is much more accessible in comparison to his paper about Computability Theory and computable numbers, which are real numbers that can be calculated with a terminating algorithm, the computable numbers are also considered countable (number of axioms for this).
This blog post won't be long, and I'll probably conclude with a link to my OneDrive account which has a copy of Alan Turing's paper. I'm going to be mostly be talking about the philosophy of Artificial Intelligence.
There is one concept which has been of great interest to philosophers since the beginning of civilization, and that is the concept of consciousness, which is the ability to be able to be aware of our own existence. This concept of consciousness is what separates us from being a very complex biological machine. In essence, our behavior is typically determined through learning and our own past experiences. Yes, we can incorporate this concept of learning into machines and measure how well it performs when learning, but a machine will never be aware of it's own existence naturally like a human, unless we find some method of enabling the machine to be aware of it's own existence, however, that would be cheating since it is still relying on predetermined behaviors created by us.
A machine is usually regarded as being intelligent if it is able to imitate a human successfully (it able to play the imitation game in Turing's paper); that is to say that a human is unable to distinguish a machine from another person. Turing outlines in his paper the similarities between a person and a computer. However, can a machine think? What is thinking? Computer programs are based upon a defined set of rules which can't be broken, unless the rules weren't correctly defined to begin with, and therefore is the machine thinking about a problem or just going based upon a defined set of rules?
Behaviorists will suggest that all thoughts are based on defined set of rules, and these rules give the false impression of free will and thought. This doesn't explain the idea of consciousness and what exactly creates consciousness. I believe machines will be able to solve mathematical problems and think, but they won't ever possess the strange and rather beautiful consciousness. Most robots aren't able to intelligently move around objects yet.
At the moment, most machines can only given Boolean valued answers to decision problems, they aren't able to think about the another answer, just give a simple "Yes" or "No" based upon some algorithm. There are learning algorithms, though I don't believe you can consider that as true thought. There is a popular idea of that a machine can only do what it is told to do, and this seems to very much true for almost all machines as of now.
I would suggest reading the paper Computing Machinery and Intelligence, which is available here.
It would be nice to hear some of my readers thoughts on the concept, and any ideas they may have about Machine Learning.
Thursday, 15 May 2014

Friday, 9 May 2014
Deterministic Polymonial Time (P) and Non-Deterministic Polymonial Time (NP)
This is going to be a short description of the difference between P and NP time complexity classes, and what the time complexity classes are based upon. These are used for Computational Complexity and Algorithm Analysis. Computability Theory is mainly concerned with what is computable, rather than how feasible that computation is.
The P and NP time complexity classes are commonly based upon Deterministic and Non-Deterministic Turing Machines. These machines use similar mathematical notation to other models of computation, but are slightly more complex and have a larger application to other areas of Computer Science, and that is one of the reasons why I prefer to look at Turing Machines rather than Finite-State Automata.
The P complexity class is a class of decision problems (Yes or No on some input), which are solvable within Polynomial Time on a Deterministic Turing Machine. It is given by P(n) or just P, where is the number of inputs. On the other hand, NP is the complexity class of decision problems which are solvable within Polynomial Time but on a Non-Deterministic Turing Machine, and therefore given by the NP(n) or simply NP notation.
In general terms, it is considered that P is a feasible complexity class for decision problems. With both classes, the running time of the algorithm is said to increase polynomially as the size of input increases.

The Y-Axis is Time, and the X-Axis is the Input Size.
NP-Completeness and NP-Hard
Given a decision problem A and another problem B, the decision problem A is considered NP-Hard, if for every B which belongs to NP, and B is reducible to A. If A is NP-Hard and and belongs to NP, then A is considered to be NP-Complete. NP-Complete algorithms infer that there is no P version of that such algorithm. They may also be considered the hardest problems within NP.
References:
NP (Complexity)
P (Complexity)
The P and NP time complexity classes are commonly based upon Deterministic and Non-Deterministic Turing Machines. These machines use similar mathematical notation to other models of computation, but are slightly more complex and have a larger application to other areas of Computer Science, and that is one of the reasons why I prefer to look at Turing Machines rather than Finite-State Automata.
The P complexity class is a class of decision problems (Yes or No on some input), which are solvable within Polynomial Time on a Deterministic Turing Machine. It is given by P(n) or just P, where is the number of inputs. On the other hand, NP is the complexity class of decision problems which are solvable within Polynomial Time but on a Non-Deterministic Turing Machine, and therefore given by the NP(n) or simply NP notation.
In general terms, it is considered that P is a feasible complexity class for decision problems. With both classes, the running time of the algorithm is said to increase polynomially as the size of input increases.
The Y-Axis is Time, and the X-Axis is the Input Size.
NP-Completeness and NP-Hard
Given a decision problem A and another problem B, the decision problem A is considered NP-Hard, if for every B which belongs to NP, and B is reducible to A. If A is NP-Hard and and belongs to NP, then A is considered to be NP-Complete. NP-Complete algorithms infer that there is no P version of that such algorithm. They may also be considered the hardest problems within NP.
References:
NP (Complexity)
P (Complexity)
Saturday, 26 April 2014
Process Directory Table Base and CR3 with Stop 0x101
This is a very simple error, and be can useful in providing a hint at which point the crash may have occurred. This has been explained by Scott Noone on this blog, but I wanted to write my own blog post about it and provide the data structure which he didn't mention. The error was found by Patrick in a Stop 0x101 bugcheck, and perfectly matches the context of the crash.
 Looking at Parameter 4, we can see the Processor Index Number which has become hung. This is where the error message is located too.
 The highlighted address is the physical address stored within the CR3 Register.
 Using the !process extension on the same Processor Number Index, we can check the DirBase field to find the mismatch within the two address indicated in the error message. The DirBase is a physical address of the Process Directory Table Base.
 The DirBase field is the field within structure formatted with !process,
which contains the address of the Process Directory Table Base for the
current process, and thus if the two addresses don't match, then WinDbg
will produce that error string. It tends to be caused when a crash
occurs during a context switch. You can find the same field under the _KPROCESS data structure:
 The Process Directory Table Base is private to each Process Address
Space and is used with conjunction to the TLB Cache and TLB Flushing.
It's all the virtual address pages which correspond to that process, and
thus when a Context Switch occurs, then the Control Register can be
changed to the address of the process and all the entries within the TLB
Cache are flushed. Afterwards, when the new addresses have been loaded, each page translation will result in a complete page walk until all the TLB Cache Entries have been rebuilt. This is a expensive process, and thus some processor architectures will tag entries corresponding to certain processes, and then only flush the corresponding tags.
References:
Process directory table base doesn't match CR3
Translation Lookside Buffer
Original Thread (Synsative) - BSOD(A clock interrupt was not recieved on a secondary processor...)
References:
Process directory table base doesn't match CR3
Translation Lookside Buffer
Original Thread (Synsative) - BSOD(A clock interrupt was not recieved on a secondary processor...)
Monday, 21 April 2014
Introduction to Detecting Anti-Debugging Techniques
Malicious Software is able to detect if it's running within a debugging environment or a debugger has been attached to the process, and thus will not generate of it's malicious behaviors in order to avoid detection from the security analyst or whoever is attempting to debug the process. In this article, I'm going to describe some of the common anti-debugging techniques which are used to detect the presence of a debugger.
NtGlobalFlag:
The NtGlobalFlag is located within the Process Environment Block (PEB) at offset 0x68 on x86 Windows, and at offset 0xBC on x64 Windows.
The default value is always 0, and doesn't change when a debugger is attached to the process. There are several methods in which the NtGlobalFlag can be changed to detect the presence of a debugger. The NtGlobalFlag contains many flags which affect the running of a process.
The most common flags which are set with NtGlobalFlag when a debugger creates a process, is the heap checking flags:
FLG_HEAP_ENABLE_TAIL_CHECK (0x10)
FLG_HEAP_ENABLE_FREE_CHECK (0x20)
FLG_HEAP_VALIDATE_PARAMETERS (0x40)
I've spoken about the purpose of these flags in a previous blog post which can be found here. These flags can be checked to detect the presence of a debugger. The general code from CodeProject, for checking the above flags:
The IsDebuggerPresent() is a Kernel32 function which will return the Boolean value of True, if a debugger is attached to the process. It can be found by checking the IAT.

It can check the BeingDebugged field of the PEB:

NtSetInformationThread() - Thread Hiding:
The NtSetInformationThread() function has a hidden undocumented parameter called ThreadHideFromDebugger (0x11), which can be used to prevent any debugging events being sent to the debugger. Debugging Events are events which will notify the debugger, these can be the creation of new threads; generation of an exception; loading and unloading of DLLs and creating child processes.
You can check if this function is imported in the IAT. PeStudio or a similar program like PeBear may check for this function.
Execution Timing:
This is a simple idea and is implies that the execution time when be slightly more with the presence of the debugger. This technique measures the execution time, and if slightly longer than usual, can imply the use of a debugger. The common instructions include:
Software Breakpoint Detection:
The instruction 0xCC - INT 3 is used to stop the execution of the debugged process and then pass the control to the debugger. The instruction is saved before the implementation of the breakpoint. Any comparison instructions (CMP, CMPXCHG) which use this instruction as a operand are considered as a anti-debugging technique.
NtGlobalFlag:
The NtGlobalFlag is located within the Process Environment Block (PEB) at offset 0x68 on x86 Windows, and at offset 0xBC on x64 Windows.
 | ||||
| Windows 7 SP1 x86 |
The most common flags which are set with NtGlobalFlag when a debugger creates a process, is the heap checking flags:
FLG_HEAP_ENABLE_TAIL_CHECK (0x10)
FLG_HEAP_ENABLE_FREE_CHECK (0x20)
FLG_HEAP_VALIDATE_PARAMETERS (0x40)
I've spoken about the purpose of these flags in a previous blog post which can be found here. These flags can be checked to detect the presence of a debugger. The general code from CodeProject, for checking the above flags:
unsigned long NtGlobalFlags = 0;

__asm {

    mov eax, fs:[30h]
    mov eax, [eax + 68h]
    mov NtGlobalFlags, eax
}


if(NtGlobalFlags & 0x70)
// 0x70 =  FLG_HEAP_ENABLE_TAIL_CHECK |
//         FLG_HEAP_ENABLE_FREE_CHECK |
//         FLG_HEAP_VALIDATE_PARAMETERS
{
    // Debugger is present
    MessageBox(NULL, TEXT("Please close your debugging " +
               "application and restart the program"),
               TEXT("Debugger Found!"), 0);
    ExitProcess(0);
}
// Normal execution
IsDebuggerPresent():The IsDebuggerPresent() is a Kernel32 function which will return the Boolean value of True, if a debugger is attached to the process. It can be found by checking the IAT.
It can check the BeingDebugged field of the PEB:
char IsDbgPresent = 0;
__asm {
     mov eax, fs:[30h]
     mov al, [eax + 2h]
     mov IsDbgPresent, al
}

if(IsDbgPresent)
{
    MessageBox(NULL, TEXT("Please close your debugging " +
               "application and restart the program"),
               TEXT("Debugger Found!"), 0);
    ExitProcess(0);
}
// Normal Execution
The CheckRemoteDebuggerPresent() is a similar function, and can be detected with the same method.NtSetInformationThread() - Thread Hiding:
The NtSetInformationThread() function has a hidden undocumented parameter called ThreadHideFromDebugger (0x11), which can be used to prevent any debugging events being sent to the debugger. Debugging Events are events which will notify the debugger, these can be the creation of new threads; generation of an exception; loading and unloading of DLLs and creating child processes.
You can check if this function is imported in the IAT. PeStudio or a similar program like PeBear may check for this function.
Execution Timing:
This is a simple idea and is implies that the execution time when be slightly more with the presence of the debugger. This technique measures the execution time, and if slightly longer than usual, can imply the use of a debugger. The common instructions include:
- RDTSC, RDPMC and RDMSR instructions.
- GetTickCount(), GetLocalTime() and GetSystemTime() are all functions within the Kernel32 library.
Software Breakpoint Detection:
The instruction 0xCC - INT 3 is used to stop the execution of the debugged process and then pass the control to the debugger. The instruction is saved before the implementation of the breakpoint. Any comparison instructions (CMP, CMPXCHG) which use this instruction as a operand are considered as a anti-debugging technique.
Friday, 18 April 2014
Debugging LPCs with WinDbg
LPCs or Local Inter-Process Communication calls are used to communicate between two User-Mode NT components, or between a User-Mode component and a Kernel-Mode Component. I believe there may be some bugchecks related to LPCs or at least problems you may potentially run into when working with LPCs if your a software engineer.
The User-Mode to Kernel-Mode communication tends to be related to security, and the User-Mode components tends to be related to creating logon sessions for the user. The terms Client and Server are used here, and this tends to refer to a different thread or different process. It depends on who created the port and who is receiving the messages. LPCs build upon the concept of IPC (Inter-Process Communication):
Methods of IPC:
The methods are usually some form of synchronization like a Semaphore, or a shared object such as a File object or Memory-Mapped File. A comprehensive list can be found on Wikipedia.
Port Creation and Port API:
With Windows Vista onwards, the LPCs have been changed to ALPCs but as far as I'm aware they still have the same structures and can still be debugged in the same way. I've taken a list of the APIs from the MSDN blog to save writing the same information:
 The messages are less than 256 bytes according to Microsoft. The messages (LPC/ALPC) are sent between the client and server. Each named port has a Security Descriptor and is able to check if it wishes to accept a connection request from a client by checking the CLIENT_ID.
 Once the Server has successfully created a named connection port with NtCreatePort, then a Client may wish to establish a connection with the connection port, whereby the Server may check the CLIENT_ID, and if it is accepted (NtAcceptConnectPort) then two new ports will be created. These ports are the Server Communication Port and the Client Communication Port. A handle will be created to the Server Communication Port and given to the Server, and a handle will be created for the Client Communication Port and given to the Client, these ports are used to send and receive messages. The Server Communication Port can terminate the connection.
Now let's examine the Port Object data structure which is used to represent a type of port with server process and owning process. Using the _LPCP_PORT_OBJECT which can we can view using WinDbg and a Kernel Memory Dump. This is allocated from paged pool.
 The ConnectionPort is a pointer to a similar data structure which is used to represent the Server Connection Port, and the ConnectedPort is used to represent the Server Communication Port.
The ClientThread is the Client's thread, and the ServerProcess is the Server's process. The LpcReplyChainHead is a doubly linked list of all the threads which are currently waiting for a reply from a sent message to that particular communication port.
The MsgQueue contains another data structure and a few additional fields of interest:
 The Sempahore is used as a signal to show that messages are waiting within the doubly linked list which is the RecieveHead field.
The ReceiveHead as stated before is a doubly linked list containing all the messages which need to be dequeued by the server.
The NonPagedPortQueue is related to the Client Communication Port and is used to track any lost replies from the Server. The fields seem to similar to the general port queue.
 The next important data structure is the _LPCP_MESSAGE structure which is allocated with paged pool, and used to track message related information between the Server and Client. This information includes Message Type, Message ID and the ClientID. We can also search through paged pool using the pool tag which is LpcM. ALPCs may use the _KALPC_MESSAGE data structure instead which contains similar information.

 The SenderPort field is the Client Communication Port. It should have a Port Object data structure associated with it.
The RepliedToThread is the Client Thread which has been replied to. The Entry field is the entry within the doubly linked list associated with the Message Queue.
The Request field is a copy of message buffer passed as a parameter with the NtRequestWaitReplyPort. The _PORT_MESSAGE data structure contains a few additional fields.

The MessageId field is a unique message identifier. The CallbackId is the the Sender ID or related to the Sender. The ClientViewSize is the size of the section created by the sender, when using Memory Mapped Files, this applies when using the NtCreateSection/CreateFileMapping and thus _PORT_VIEW data structure.
 The DataLength and the TotalLength fields are associated with the length of the data within the message and the header, and the TotalLength includes the size of the _PORT_MESSAGE structure.
We can check the _EPROCESS and _ETHREAD fields for information related to LPCs.
Let's begin with the _EPROCESS data structure which contains three LPC ports, which each have their own function within the Windows operating system:
 The DebugPort is used for sending debugging messages (User-Mode), the ExceptionPort is used with CsrCreateProcess and used to create a new process with a connection with the debugging port. _LPC_EXCEPTION message is sent using this port when a thread doesn't catch a exception. The SecurityPort is used by the lasass.exe process for security purposes.
Using the -y switch to set some search query parameter, we need to search the _ETHREAD data structure for some LPC fields. On Windows Vista and later systems, some of the fields seems to have been removed. Windows XP will have the original LPC fields.
 AlpcMessageId is the message sent to the Server while the Client Thread waits for a response. The AlpcMessage is a pointer to the message data structure seen earlier or I assume it to be. The AlpcWaitListEntry is a list of threads waiting for a reply from the Server communication or connection port depends upon the situation. The AlpcWaitSempahore causes a Client Thread to wait while the Server processes the message received.
The original Windows XP fields are described in the table below:
 WinDbg Debugger Extensions:
The ALPC extensions do not seem to be documented within the WinDbg documentation, but the !lpc debugger extensions are documented. !lpc only applies to Windows XP and earlier. Windows Vista onwards will need to use the ALPC extensions which are limited in comparison.
 I'm using the !alpc version of the debugger extension, but the !lpc extension seems to have more functionality such as the PoolSearch option, but you could try it with the !poolfind extension and the pooltag.
 I've just chosen a random process, and then passed it as a parameter to the !alpc /lpp debugger extension to view which ports the process is connected to, and which ports were created by the process.
The address next to the process name appears to be the Process Address, and the first address (85eb9378) seems to be the Client Communication Port address, and the second address seems to be the address of the ApiPort. The !alpc /p extension helps to clarify this information. The 38 on the last line indicates the number of messages within the pending queue.
 We can view message information with the !alpc /m extension:
 The !lpc debugger extension documentation can be found in WinDbg, the !alpc extensions didn't have information, and therefore my assumptions on the fields were through investigation and knowledge from Microsoft related resources which will be added to the References section.
Common Issues:
By doing some research, I've manged to find some information on the common issues related to LPCs.
References:
LPC Communication
The User-Mode to Kernel-Mode communication tends to be related to security, and the User-Mode components tends to be related to creating logon sessions for the user. The terms Client and Server are used here, and this tends to refer to a different thread or different process. It depends on who created the port and who is receiving the messages. LPCs build upon the concept of IPC (Inter-Process Communication):
Methods of IPC:
The methods are usually some form of synchronization like a Semaphore, or a shared object such as a File object or Memory-Mapped File. A comprehensive list can be found on Wikipedia.
Port Creation and Port API:
With Windows Vista onwards, the LPCs have been changed to ALPCs but as far as I'm aware they still have the same structures and can still be debugged in the same way. I've taken a list of the APIs from the MSDN blog to save writing the same information:
Now let's examine the Port Object data structure which is used to represent a type of port with server process and owning process. Using the _LPCP_PORT_OBJECT which can we can view using WinDbg and a Kernel Memory Dump. This is allocated from paged pool.
The ClientThread is the Client's thread, and the ServerProcess is the Server's process. The LpcReplyChainHead is a doubly linked list of all the threads which are currently waiting for a reply from a sent message to that particular communication port.
The MsgQueue contains another data structure and a few additional fields of interest:
The ReceiveHead as stated before is a doubly linked list containing all the messages which need to be dequeued by the server.
The NonPagedPortQueue is related to the Client Communication Port and is used to track any lost replies from the Server. The fields seem to similar to the general port queue.
Here's the data structure for the message:
The RepliedToThread is the Client Thread which has been replied to. The Entry field is the entry within the doubly linked list associated with the Message Queue.
The Request field is a copy of message buffer passed as a parameter with the NtRequestWaitReplyPort. The _PORT_MESSAGE data structure contains a few additional fields.
The MessageId field is a unique message identifier. The CallbackId is the the Sender ID or related to the Sender. The ClientViewSize is the size of the section created by the sender, when using Memory Mapped Files, this applies when using the NtCreateSection/CreateFileMapping and thus _PORT_VIEW data structure.
We can check the _EPROCESS and _ETHREAD fields for information related to LPCs.
Let's begin with the _EPROCESS data structure which contains three LPC ports, which each have their own function within the Windows operating system:
Using the -y switch to set some search query parameter, we need to search the _ETHREAD data structure for some LPC fields. On Windows Vista and later systems, some of the fields seems to have been removed. Windows XP will have the original LPC fields.
The original Windows XP fields are described in the table below:
The ALPC extensions do not seem to be documented within the WinDbg documentation, but the !lpc debugger extensions are documented. !lpc only applies to Windows XP and earlier. Windows Vista onwards will need to use the ALPC extensions which are limited in comparison.
The address next to the process name appears to be the Process Address, and the first address (85eb9378) seems to be the Client Communication Port address, and the second address seems to be the address of the ApiPort. The !alpc /p extension helps to clarify this information. The 38 on the last line indicates the number of messages within the pending queue.
Common Issues:
By doing some research, I've manged to find some information on the common issues related to LPCs.
- Servers aren't able to send messages for Clients which are waiting for a LPC Message.
- There is no Timeout for LPC Wait APIs (this may have changed).
- If the Server Process is terminated, then the Client Threads aren't notified unless there were Client Threads waiting for a reply from that Server Process.
- The Server replied to the wrong Client, and the Server threads are completely deadlocked and thus can't process any more requests from Clients to a particular port.
References:
LPC Communication
Tuesday, 15 April 2014
Understanding Memory Probes - A Quick Introduction
You may notice with Stop 0x50, there is the mentioning of something called the memory probe, the memory probe is a type of function which is used to check that a buffer (chunk of virtual memory) resides within user-mode and is correctly aligned to a boundary. I've spoken about memory alignment before in a previous blog post, however, I will mention the topic again in post.
Memory Alignment is very useful for performance in processors, if data is aligned to a certain boundary, then larger chunks of data can be accessed much more efficiently rather than lots of small accesses with a large chunk of data. Data misalignment is a common problem with debugging, especially with x64 processors.
We can check for alignment issues by checking the EFLAGS register and AC flag, which when set to 1, will mean that data being accessed must be aligned to the correct boundary otherwise you'll experience access violations and potential BSODs.On the other hand, using malloc or new should always create aligned data accesses.
Supposedly, the interrupt handler is assigned the 17h vector number within the IDT table.
 Now, lets move onto the concept of a try-except block, and the Probe. The Memory Probe has to reside within the try-except block to be able to raise the appropriate exception code to the operating system. The two versions of Memory Probes are the ProbeForRead and ProbeForWrite. Memory Probes can't be used within the Kernel Mode Address Range otherwise it will lead to an exception.
The try-except block is a block of code which tested to see if it will run properly, and if it doesn't then a exception handler will be invoked.

I've created a very quick template for a try-except block which will catch all exceptions regardless of their type, in real programs you'll most likely have specific handlers for exception errors. Typically, inside the catch block, the code will producing a error message to the user. The try block is the code we're attempting to execute with no problems.
The ProbeForRead function takes three parameters: the starting address of the buffer, the length of the buffer and the required alignment.
 Memory Probes are used within the win32k.sys subsystem (Kernel-Mode) when dealing with System Calls from User-Mode and storing certain libraries within User-Mode. The Win32k.sys has it's own SSDT called the Shadow SSDT. This article may also be useful for information on SSDT Hooking.
Memory Alignment is very useful for performance in processors, if data is aligned to a certain boundary, then larger chunks of data can be accessed much more efficiently rather than lots of small accesses with a large chunk of data. Data misalignment is a common problem with debugging, especially with x64 processors.
We can check for alignment issues by checking the EFLAGS register and AC flag, which when set to 1, will mean that data being accessed must be aligned to the correct boundary otherwise you'll experience access violations and potential BSODs.On the other hand, using malloc or new should always create aligned data accesses.
Supposedly, the interrupt handler is assigned the 17h vector number within the IDT table.
The try-except block is a block of code which tested to see if it will run properly, and if it doesn't then a exception handler will be invoked.
I've created a very quick template for a try-except block which will catch all exceptions regardless of their type, in real programs you'll most likely have specific handlers for exception errors. Typically, inside the catch block, the code will producing a error message to the user. The try block is the code we're attempting to execute with no problems.
The ProbeForRead function takes three parameters: the starting address of the buffer, the length of the buffer and the required alignment.
Friday, 11 April 2014
Debugging Stop 0x50 - A Few Little Clues
This is the first time I've debugged in a while, and the example is from a dump file which my friend on Sysnative Patrick has been debugging, but I wanted to write another debugging post which explained a few additional clues you can check with Stop 0x50's.
The problem which I find with some bugchecks, is that their names can be a little generic and not really pinpoint the exact problem. Yes, they give a idea of the problem but do not give any major clues; a paged pool address could have been referenced at the wrong IRQL Level which would likely lead to a Stop 0x50 or a Stop 0xA. Let's take a look at few of the little clues available within the dump file.
Within the description there is two clues which point to the type of possible problem. A invalid system address was being referenced, which is quite obvious, since it must have been a Kernel-Mode address otherwise we wouldn't have gotten the bugcheck and the address has been freed. Of course, the address could have been paged out onto a page file, and then the corruptions within the file system may have lead to that address being corrupted too.
 Now, a good thing next would be to check the CR2 and this if that matches the address being referenced within Arg 1. The CR2 register or Control Register 2, is the register which contains the Page Fault Linear Address or the last address which the program attempted to access. Linear Address is pretty much the Virtual Address or the Logical Address with the segment register added, which in this case is DS (Data Segment).
 The CR2 register being to be pointing to the referenced address within Arg 1. We can investigate further and gather some small but important clues by gathering a stack trace and then viewing the registers stored within a context switch upon a page fault.
 Using the .trap command on the trap frame address, we can view the registers and referenced addresses and the last called function which caused the page fault. Note a trap frame is the saving of a register state when an exception occurs, which is what a page fault is technically considered, it would only lead to problems if the exception couldn't be handled by the page fault handler within MmAccessFault.
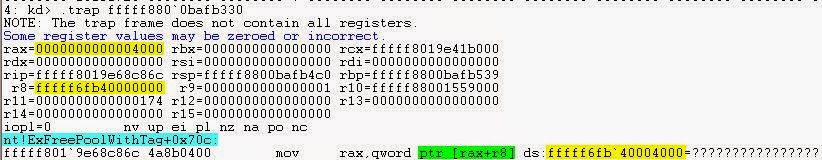 The concatenation of the two registers provides the address within the ds register and the referenced address within CR2 and Arg 1 of the bugcheck description. We have found the referenced address. Going back to the bugcheck description, notice "pointing to freed memory", the memory address has been freed wrongly with the nt!ExFreePoolWithTag function and paged out back onto the disk when it shouldn't have since this a non-paged pool memory address.
We can even check the IRQL Level with the !irql extension, and see if the problem could have been due to IRQL Level problems, since only non-paged pool can be accessed and any page faults are illegal. Since the IRQL Level was 0, then the possibility of the IRQL Level is moot as page faults are legal.
 In my opinion, the problem is most likely to point to software issues. It's been a while since I last debugged, so it was nice to be able to write a blog post regarding the subject again.
The full thread is here with Patrick's analysis.
The problem which I find with some bugchecks, is that their names can be a little generic and not really pinpoint the exact problem. Yes, they give a idea of the problem but do not give any major clues; a paged pool address could have been referenced at the wrong IRQL Level which would likely lead to a Stop 0x50 or a Stop 0xA. Let's take a look at few of the little clues available within the dump file.
Within the description there is two clues which point to the type of possible problem. A invalid system address was being referenced, which is quite obvious, since it must have been a Kernel-Mode address otherwise we wouldn't have gotten the bugcheck and the address has been freed. Of course, the address could have been paged out onto a page file, and then the corruptions within the file system may have lead to that address being corrupted too.
We can even check the IRQL Level with the !irql extension, and see if the problem could have been due to IRQL Level problems, since only non-paged pool can be accessed and any page faults are illegal. Since the IRQL Level was 0, then the possibility of the IRQL Level is moot as page faults are legal.
The full thread is here with Patrick's analysis.
Subscribe to:
Posts (Atom)